A list in Python holds an ordered sequence of items, written between square brackets. It can hold anything, and it can be changed after it’s created.
fruits = ["apple", "banana", "orange"]print(fruits[0])    # 'apple'
print(len(fruits))  # 3
That mutability is what makes lists useful and what causes their sharpest bugs — two variables can point at the same list without you noticing, and a copy may not be as separate as it looks.
This guide covers creating and accessing lists, the methods worth knowing, the copy trap, and the one-line way to build a list that replaces most loops.
| Written with | Square brackets, items separated by commas |
| First index | 0 — and -1 is the last |
| Mutable | Yes — unlike strings and tuples |
sort() returns | None — it modifies in place |
| The trap | b = a doesn’t copy — both names point at one list |
Creating a list
empty = []
fruits = ["apple", "banana"]
mixed = [1, "text", True, None, [2, 3]]
A list can hold any types together, including other lists — Python doesn’t require them to match.
⚠️ One thing that doesn’t work: you can’t assign to a position that doesn’t exist yet.
fruits = []
fruits[0] = "apple"
# IndexError: list assignment index out of rangefruits.append("apple")   # this is how you add to an empty list
A list has to grow through append() or insert() — indexing only reaches positions that already exist.
Accessing items
numbers = [10, 20, 30, 40, 50]numbers[0]     # 10   ← first
numbers[2]     # 30   ← third
numbers[-1]    # 50   ← last
numbers[-2]    # 40   ← second from the end
Counting starts at zero, so the third item is at index 2. Negative indices count backwards, and -1 is always the last item regardless of length.
Slicing takes a range:
numbers[1:4]    # [20, 30, 40]   ← from 1 up to, not including, 4
numbers[:3]     # [10, 20, 30]
numbers[2:]     # [30, 40, 50]
numbers[::-1]   # [50, 40, 30, 20, 10]   ← reversed copy
⚠️ Indexing past the end raises; slicing doesn’t.
numbers[10]     # IndexError: list index out of range
numbers[1:99]   # [20, 30, 40, 50]   ← no error
Adding and removing
Adding
items = [1]items.append([2, 3])   # [1, [2, 3]]   ← one item, which is a list
items = [1]
items.extend([2, 3])   # [1, 2, 3]     ← each item separately
items.insert(1, 99)    # [1, 99, 2, 3] ← at a position
append() adds one thing; extend() adds each thing. Our guide on append() covers the difference in full.
⚠️ insert(0, x) is slow on long lists — every existing item shifts one position. For adding at the front frequently, collections.deque is O(1) at both ends.
Removing
numbers = [1, 2, 3, 2]numbers.pop()       # 2   ← removes the last AND returns it
numbers.pop(0)      # 1   ← removes by index, returns it
numbers.remove(2)   # removes the FIRST 2, returns None
del numbers[0]      # removes by index, returns nothing
The distinction that matters:
pop() removes by index and returns what it removed.remove() removes by value — the first match only — and returns None.
values = [1, 2, 3, 2]
values.remove(2)
print(values)   # [1, 3, 2]   ← only the first 2 went
And both raise when they can’t do the job:
[].pop()            # IndexError: pop from empty list
[1, 2].remove(99)   # ValueError: list.remove(x): x not in list
⚠️ sort() returns None
This is the most common bug with lists.
numbers = [3, 1, 2]
numbers = numbers.sort()print(numbers)   # None   ← the list is gone
sort() sorts in place and returns nothing. The assignment stored None, and the list was lost — with no error at that line.
Two correct forms:
numbers.sort()              # modifies numbers, no assignment
new = sorted(numbers)       # returns a new list, original untouched
The same applies to reverse(), append(), extend(), insert(), remove() and clear() — all of them return None. ⚠️ Our guide on methods that return None has the full list.
Sorting with a key
words = ["bb", "a", "ccc"]sorted(words, key=len)              # ['a', 'bb', 'ccc']
sorted([3, 1, 2], reverse=True)     # [3, 2, 1]people = [("Ana", 30), ("Joao", 25)]
sorted(people, key=lambda p: p[1])  # [('Joao', 25), ('Ana', 30)]
key takes a function applied to each item before comparing — it’s how you sort objects, tuples or dictionaries by a specific field.
⚠️ The copy trap
This one produces bugs that look impossible.
a = [1, 2]
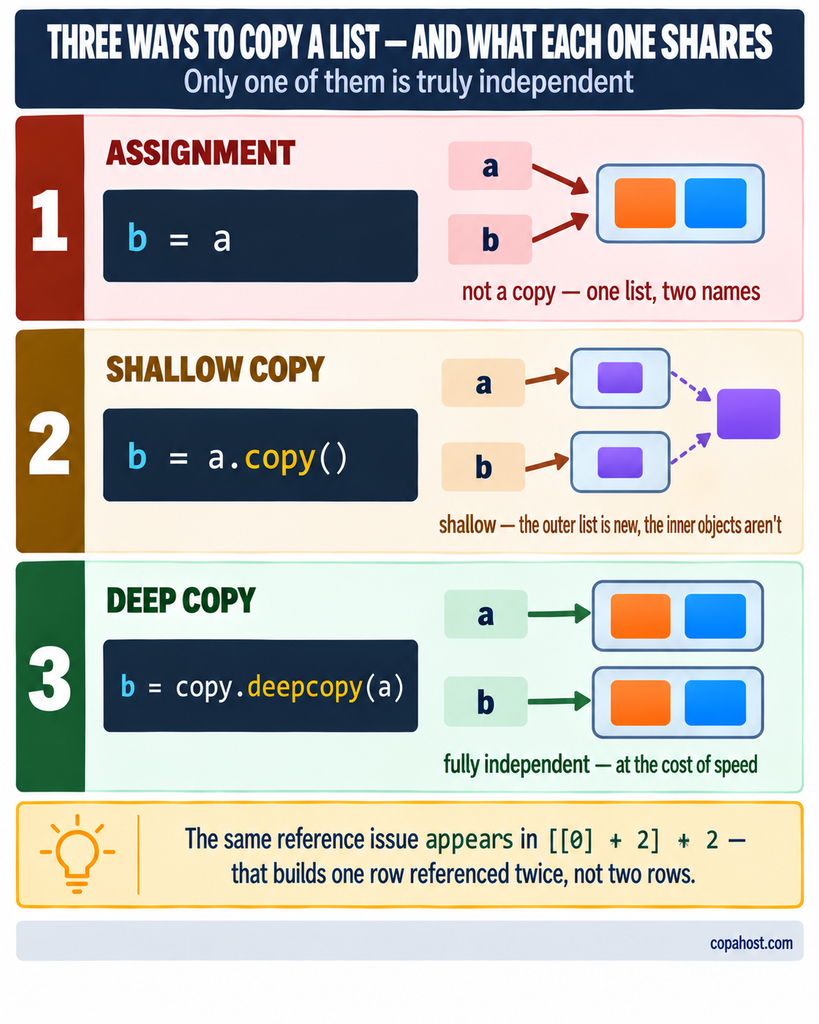
b = a              # NOT a copy
b.append(3)print(a)   # [1, 2, 3]   ← a changed too
b = a creates a second name for the same list, not a second list. Anything done through either name is visible through both.
.copy() makes a shallow copy
a = [1, 2]
b = a.copy()       # or list(a), or a[:]
b.append(3)print(a)   # [1, 2]   ← independent now
That solves the simple case. But with nested lists it doesn’t:
a = [[1], [2]]
b = a.copy()
a[0].append(99)print(b)   # [[1, 99], [2]]   ← the inner list is still shared
.copy() copies the outer list; the inner objects are still the same objects.
For full independence, deepcopy():
import copya = [[1], [2]]
b = copy.deepcopy(a)
a[0].append(99)print(b)   # [[1], [2]]   ← truly independent
⚠️ deepcopy() is slower and recurses through everything — use it only when the structure is nested and you need the separation.
List comprehensions
The one-line form that replaces most loops.
# With a loop
doubled = []
for x in range(5):
doubled.append(x * 2)# With a comprehension
doubled = [x * 2 for x in range(5)]   # [0, 2, 4, 6, 8]
With a filter:
evens = [x for x in range(10) if x % 2 == 0]   # [0, 2, 4, 6, 8]names = ["  Ana  ", "  Joao  "]
cleaned = [n.strip() for n in names]           # ['Ana', 'Joao']
It’s shorter, faster, and what most Python developers expect to see.
⚠️ Keep the explicit loop when the body has several statements, or when the logic is complex enough that one line would hurt readability. A comprehension that needs a comment is a loop in disguise.
Lists of lists
matrix = [
[1, 2, 3],
[4, 5, 6],
[7, 8, 9],
]matrix[0][1]   # 2   ← row 0, column 1
matrix[2][0]   # 7
Two indices: the first picks the inner list, the second picks the item in it.
⚠️ The trap when creating one
grid = [[0] * 2] * 2
grid[0][0] = 9print(grid)   # [[9, 0], [9, 0]]   ← both rows changed
* 2 on the outer list repeated the same row twice — not two rows, one row referenced twice. Changing one changes “both”, because there is only one.
The correct form uses a comprehension:
grid = [[0] * 2 for _ in range(2)]
grid[0][0] = 9print(grid)   # [[9, 0], [0, 0]]   ← independent rows
Each iteration builds a fresh inner list. ⚠️ This is the same reference issue as the copy trap, in a place nobody expects it.
Useful patterns
# Looping with the index
for i, fruit in enumerate(["apple", "banana"]):
print(i, fruit)          # 0 apple / 1 banana# Two lists in parallel
for name, age in zip(["Ana", "Joao"], [30, 25]):
print(name, age)# Unpacking
x, y, z = [1, 2, 3]# Counting and finding
[1, 2, 2, 3].count(2)   # 2
[1, 2, 3].index(2)      # 1
2 in [1, 2, 3]          # True# Removing duplicates, preserving order
list(dict.fromkeys([1, 2, 2, 3]))   # [1, 2, 3]
⚠️ Prefer enumerate() to range(len(items)) — it’s the clearest sign of someone writing Python with another language’s habits.
Lists, tuples and sets
| Type | Syntax | When to use |
|---|---|---|
| list | [1, 2] | Order matters and the contents change |
| tuple | (1, 2) | Order matters and nothing should change |
| set | {1, 2} | No duplicates, and order doesn’t matter |
Two practical differences beyond style:
A tuple can be a dictionary key; a list can’t. Mutable objects aren’t hashable.
And membership testing in a set is much faster — x in my_set is constant time, while x in my_list scans the whole list. ⚠️ On a list of a hundred thousand items checked repeatedly, that’s the difference between instant and noticeably slow.
Where lists bite on a server
Two failures that appear only with real volume.
Memory. A list holds every item at once, so reading a large file into one loads the whole thing. ⚠️ On a shared plan with a memory cap, the process is killed with no traceback — the log is empty because there was no exception to write. For large files, iterate line by line rather than collecting.
And the mutable default argument. This one corrupts data silently across calls:
def add_item(item, items=[]):
items.append(item)
return itemsadd_item("a")   # ['a']
add_item("b")   # ['a', 'b']   ← the list was not empty
Default arguments are evaluated once, when the function is defined — so there’s a single list shared by every call, growing forever.
def add_item(item, items=None):
if items is None:
items = []
items.append(item)
return items
⚠️ In a long-running process — a web application, a worker — that list accumulates across requests, which is both a memory leak and a data leak between users.
A mutable default argument in a long-running worker accumulates forever — and on a shared plan the process is killed before you see a traceback. Copahost VPS plans give you dedicated memory, root access, and logs you can actually read. From €3.99/month, with snapshots.
See VPS plansFrequently asked questions
How do I create a list in Python?
With square brackets and commas: fruits = ["apple", "banana"]. An empty list is []. ⚠️ You can’t assign to a position that doesn’t exist yet — fruits[0] = "apple" on an empty list raises IndexError. Use append() to grow it.
What’s the difference between append() and extend()?
append() adds one item, whatever it is — appending a list produces a nested list. extend() iterates over what you give it and adds each element separately. So [1].append([2,3]) gives [1, [2, 3]] and extend gives [1, 2, 3].
Why did my list become None after sorting?
Because sort() sorts in place and returns None, so numbers = numbers.sort() stores None. Call numbers.sort() on its own line, or use sorted(numbers), which returns a new list.
What’s the difference between pop() and remove()?
pop() removes by index and returns the item — pop() with no argument takes the last. remove() removes by value, only the first match, and returns None. ⚠️ Both raise if they can’t: IndexError for an empty list, ValueError for a value that isn’t there.
Why does changing one list change another?
Because b = a doesn’t copy — it creates a second name for the same list. Use a.copy(), list(a) or a[:] for an independent one.
Why isn’t .copy() enough for nested lists?
Because it’s a shallow copy: the outer list is new, but the inner objects are the same objects. Modifying an inner list shows up in both. Use copy.deepcopy() when the structure is nested and you need real separation.
Why does changing one row of my 2D list change all of them?
Because [[0] * 2] * 2 repeats the same inner list, rather than creating two. There’s only one row, referenced twice. Build it with a comprehension instead: [[0] * 2 for _ in range(2)].
What’s a list comprehension?
A one-line way to build a list: [x * 2 for x in range(5)]. It replaces a loop with append(), runs faster, and is what most Python developers expect. ⚠️ Keep the explicit loop when the body needs several statements.
When should I use a tuple instead of a list?
When the contents shouldn’t change. A tuple is immutable, slightly lighter, and can be used as a dictionary key — a list can’t, because mutable objects aren’t hashable. For fixed records like coordinates or database rows, a tuple signals intent.
How do I remove duplicates from a list?
list(set(values)) is shortest but loses the order. list(dict.fromkeys(values)) preserves it, and is usually what you want.
Is checking in on a list slow?
On a large one, yes — x in my_list scans item by item. A set does the same check in constant time, so if you’re testing membership repeatedly against many items, convert once and test against the set.
Why is a mutable default argument dangerous?
Because defaults are evaluated once, when the function is defined — so def f(items=[]) shares one list across every call, and it grows forever. ⚠️ In a long-running web process, that accumulates across requests. Use =None and create the list inside the function.
Conclusion
A list in Python is an ordered, mutable sequence — and that mutability is both why it’s useful and where its worst bugs come from.
Three things carry it. sort() and the other in-place methods return None, so x = x.sort() destroys the list. b = a is not a copy — it’s a second name for the same list, and even .copy() is shallow when the contents are nested. And [[0] * 2] * 2 builds one row referenced twice, which is the same reference issue in a place nobody expects.
And the one that only shows up in production: a mutable default argument shares a single list across every call. In a script that runs once, it’s a curiosity. In a web process handling requests for days, it’s a memory leak and a data leak at the same time.
